Podcasting guides
September 21, 2026


Object-based audio stores each sound source as its own file, with metadata describing where it sits in space, how loud it plays, and what it is. The listener's device renders the final mix at playback, so one deliverable adapts to headphones, a soundbar, or a theater. Dolby Atmos is the best-known object-based format.
The mix moves out of the studio and into the playback device. That is the whole idea. In a conventional stereo podcast, I decide how loud the music sits under the host and every listener gets my decision, on studio monitors and on a phone speaker on a train alike. In an object-based deliverable, the host's voice, the guest's voice, the music, and the room ambience travel as separate objects with metadata, and the listener's player assembles them on the spot.
Separation at playback opens doors that a printed mix keeps shut. A listener could turn up the narrator to hear them over incidental music, mute the commentary on a sports stream, or switch the dialogue language without downloading a different episode. The renderer can also adapt: compress dynamics on a noisy commute, open them back up on good headphones at home. We have been mixing defensively for the worst playback environment for decades, and object-based delivery removes that compromise because the format carries the ingredients instead of the finished dish.
The three models answer the same question differently: what does the file actually store? Channel-based audio stores speaker feeds. Scene-based audio, usually called ambisonics, stores a mathematical description of the full sound field around a single point. Object-based audio stores individual sources plus instructions. Most modern immersive formats mix the three.
| Model | What it stores | Examples | Strength | Limit |
|---|---|---|---|---|
| Channel-based | Fixed speaker feeds | Stereo, 5.1, 7.1 | Universal playback, simple tooling | Mix locked to one speaker layout |
| Object-based | Separate sources plus positional metadata | Dolby Atmos objects, MPEG-H | Adapts to any system, listener control | Needs a renderer; larger deliverables |
| Scene-based | Full sound field around one point (ambisonics) | First-order B-format, 360 video audio | Captures real acoustic space, rotates freely for VR | Individual sources cannot be isolated after capture |
Ambisonics deserves one clarification because the terms get tangled. An ambisonic recording is a scene: everything around the microphone array, encoded together. You can rotate the whole scene, but you cannot reach in and pull out one voice. Object-based workflows solve that by recording the voices separately and laying the ambisonic material underneath as a bed, a technique we cover in creating immersive soundscapes with Nomono.
Dolby Atmos is a hybrid, and that surprises people who assume it is objects all the way down. An Atmos mix carries a channel-based bed, typically 7.1.2, plus up to 118 dynamic objects with positional metadata, per Dolby's own production documentation (Dolby, 2024). The renderer in the playback device, from cinema processor to phone, places each object using whatever speakers exist. One master serves every environment.
For spoken-word producers, Atmos matters because the distribution rails already exist. Apple Podcasts and Amazon Music both accept Dolby Atmos content, and AirPods render it binaurally over plain headphones, no ceiling speakers required. Our post on spatial audio for podcasts covers that pipeline from the capture side.
Hearing-impaired listeners gain the most immediate benefit. When dialogue travels as its own object, a player can let the listener push music and sound design down and dialogue up, or mute the background entirely. Metadata can also rank content priority: dialogue first, sound design second, incidental music third, so a renderer makes sensible choices on its own. Transcripts stored as object metadata line up with the specific voice that spoke them, which makes navigation by transcript accurate. Once a mix is printed to stereo, the ingredients are gone and none of this works.
Each object can carry its own descriptive metadata, beyond today's episode-level title and artwork. A guest's voice object can hold their name, the recording location, and a short bio, which would let platforms answer searches like "every episode this person appeared on" directly from the audio files. Language switching works the same way: alternative dialogue objects ride inside one deliverable, and the player swaps them in real time. One episode, one URL, one set of analytics, every language. Producers maintaining separate translated feeds today will see the appeal.
360 producers already live in the scene-based world, and objects complete it. An ambisonic bed gives you the rotating environment, while tracked voice objects stay pinned to the person as the viewer looks around. We learned this the slow way on early immersive projects, where a voice baked into the scene smeared across the image the moment anyone turned their head; the write-up is in creating immersive content: lessons learned.
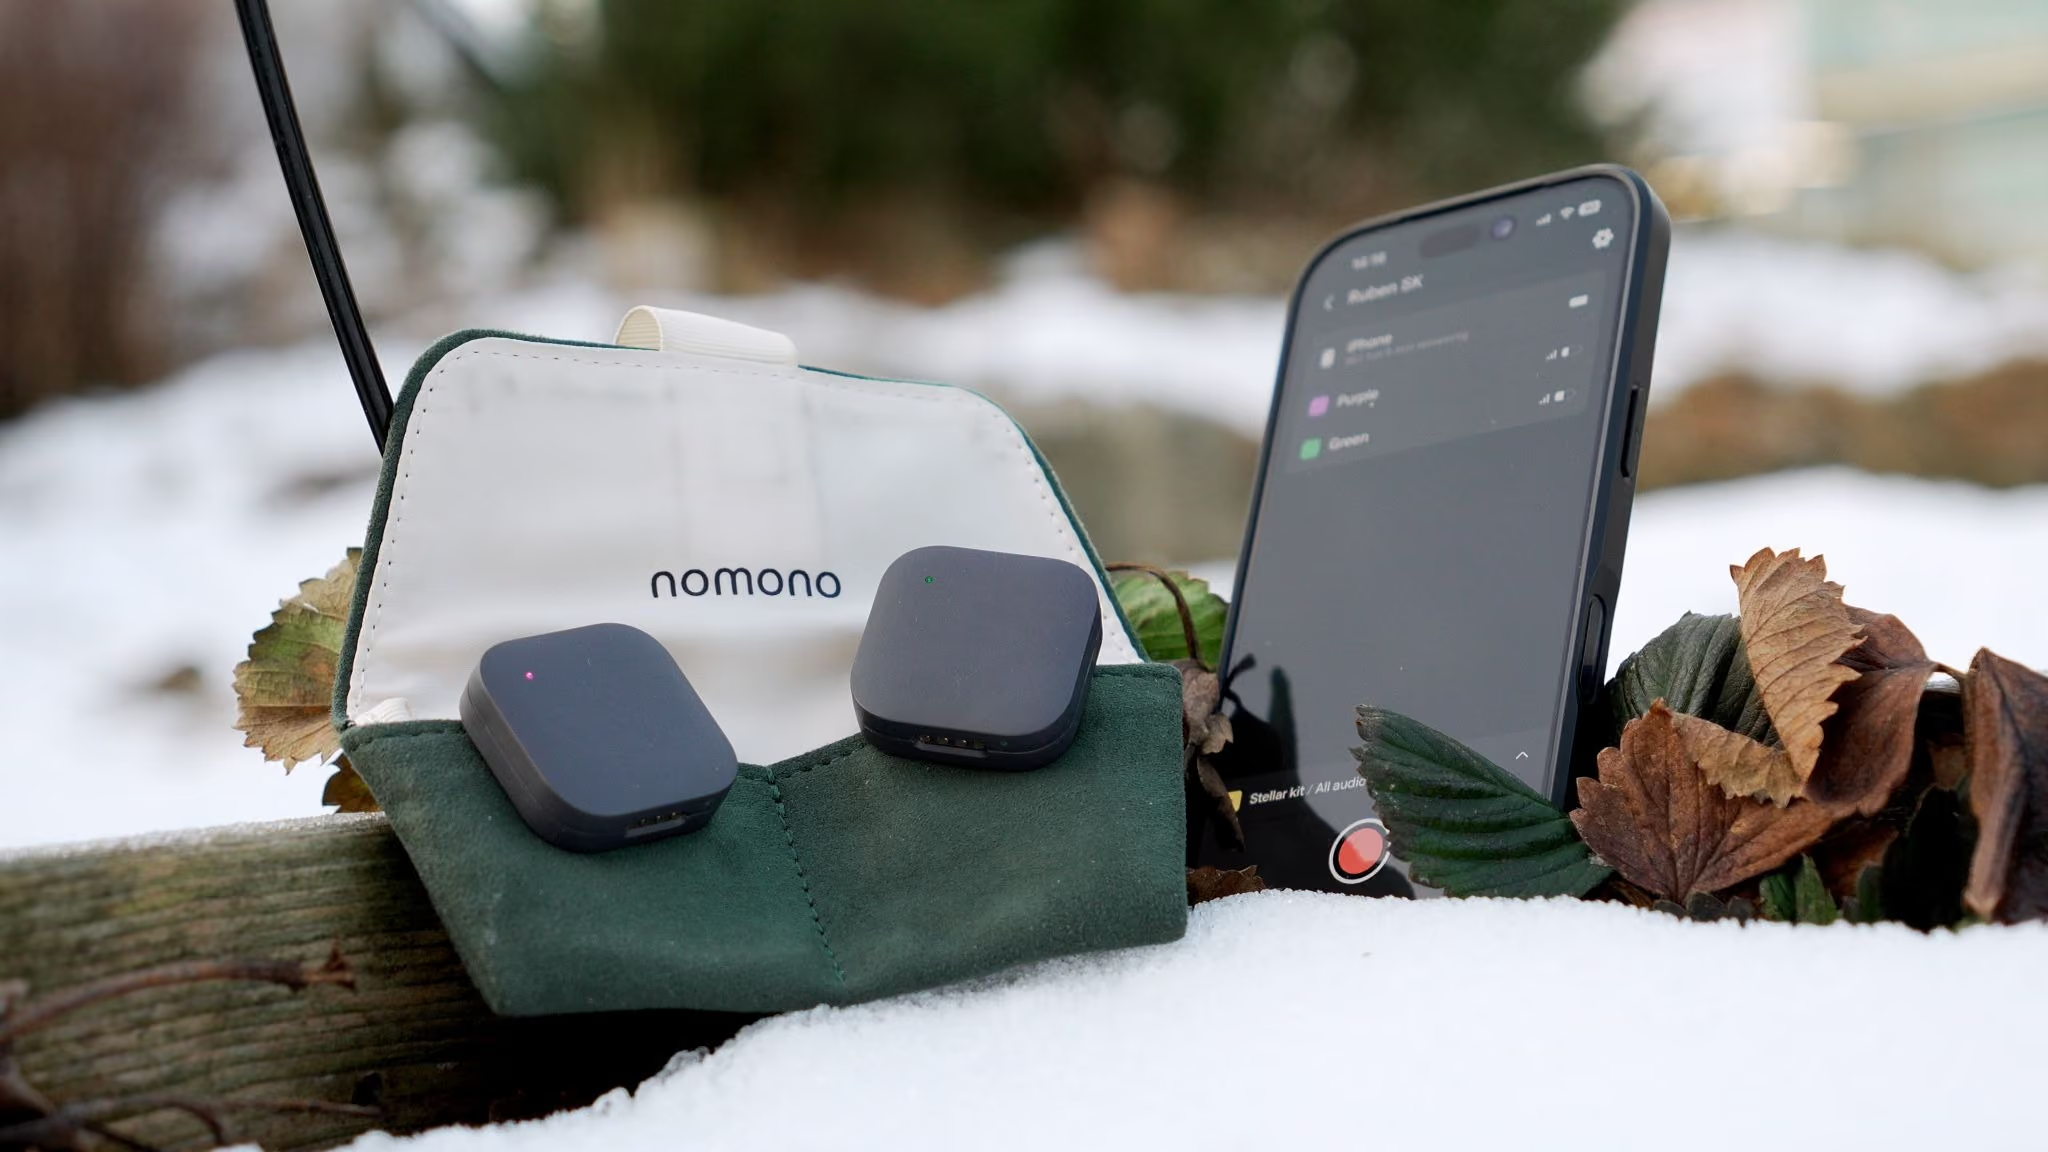
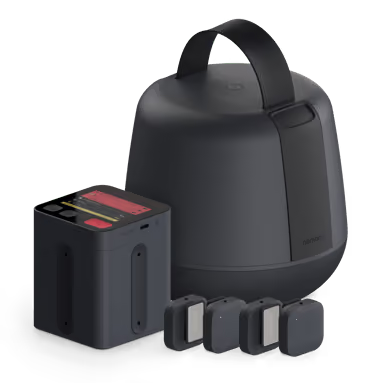
The Sound Capsule records object-based source material by design, even if you never open an Atmos session. Each of the four Stellar wireless lav mics produces a discrete mono WAV: those are your voice objects, one per speaker, position-tracked relative to the Space Recorder. The Space Recorder's eight-microphone array simultaneously captures a four-track first-order ambisonic WAV: that is your scene-based bed, the real acoustic space you recorded in.
Tracked objects plus an ambisonic bed is the structure a Dolby Atmos or MPEG-H mix wants as input. Studio Cloud handles the cloud side: enhancement, editing, and export of the individual stems, so the separation survives all the way to your mix. Stereo-only producers still benefit, since isolated tracks fix problems a printed mix cannot, and anyone moving to spatial finds the hard part already done at capture. The full workflow is documented at spatial audio with Nomono.
Distribution remains the honest caveat. Standard RSS podcast feeds carry stereo files, and most podcast players render nothing else, so object-based spoken-word content currently reaches listeners through platform-specific routes: Dolby Atmos on Apple Podcasts and Amazon Music, MPEG-H on some broadcast services, ambisonics on YouTube 360. A producer publishing today should plan a stereo deliverable alongside the object-based one. Recording separated sources costs nothing extra with the right kit, and a stereo mix can always be printed from objects. The reverse is impossible.
Object-based audio stores each sound source as a separate file with metadata describing its position, level, and identity, and the listener's device renders the final mix at playback. One deliverable adapts to headphones, soundbars, or full speaker arrays. Dolby Atmos is the most widely used object-based format.
Channel-based audio stores finished speaker feeds, so a stereo file is locked to two channels forever. Object-based audio stores the individual sources plus instructions, and the playback device builds the mix to suit whatever speakers or headphones are present. The practical difference is flexibility after delivery: objects can be repositioned, rebalanced, or swapped, while channels cannot.
Dolby Atmos is one implementation of object-based audio, and a hybrid one. An Atmos master combines a channel-based bed with up to 118 positional objects (Dolby, 2024). Other object-based formats exist, MPEG-H being the main broadcast alternative, but Atmos has the widest consumer reach.
Scene-based audio, usually delivered as ambisonics, encodes the entire sound field around a single point rather than separate sources or speaker feeds. A first-order ambisonic file describes sound arriving from every direction in four channels, and the scene rotates with a viewer's head, which is why 360 video platforms use it. Individual sources cannot be isolated after capture.
Podcasts can publish object-based audio now through Dolby Atmos on Apple Podcasts and Amazon Music, rendered binaurally on ordinary headphones. Standard RSS feeds still carry stereo only, so most producers publish both versions. Recording with separated sources keeps the spatial option open even if you publish stereo first.
No special headphones are required. The renderer in the phone or player folds the objects down to binaural stereo, so any headphones reproduce the spatial positioning, and AirPods add head tracking on top. Speaker playback is the exception: placing objects across physical speakers needs an Atmos-capable soundbar or receiver.
The Sound Capsule records four discrete voice tracks and a spatial bed at the same time. Each Stellar wireless lav produces its own mono WAV, and the Space Recorder's eight-microphone array captures a four-channel ambisonic WAV of the surrounding space. Tracked voice objects plus an ambisonic bed is the source structure a Dolby Atmos mix is built from.
Accessibility improves because dialogue stays separable at playback. A hearing-impaired listener can raise the voices and lower the music, or mute the background entirely, choices a printed stereo mix removes. Priority metadata lets players make those adjustments automatically, and per-object transcripts tie text to the exact voice that spoke it.
Ruben Åeng is Lead Audio Engineer at Nomono, where he works on spatial capture and the processing pipeline behind Studio Cloud.
Enjoy free express shipping to the listed locations within 2–5 business days.
 Austria
 Belgium
 Bulgaria
 Croatia
 Cyprus
 Czech Republic
 Denmark
 Estonia
 Finland
 France
 Germany
 Greece
 Hungary
 Ireland
 Italy
 Latvia
 Lithuania
 Luxembourg
 Malta
 Netherlands
 Norway
 Poland
 Portugal
 Romania
 Slovakia
 Slovenia
 Spain
 Sweden
 United Kingdom
 United States